
An autonomous document factory
Lector takes over the processing of incoming documents — end to end, traceable and scalable. Not an OCR tool. Not a rule set. Genuine document understanding.
What can Lector do?
More than reading.Understanding and acting.
Lector combines document understanding, context analysis and autonomous processing, and delivers structured results straight into your systems.
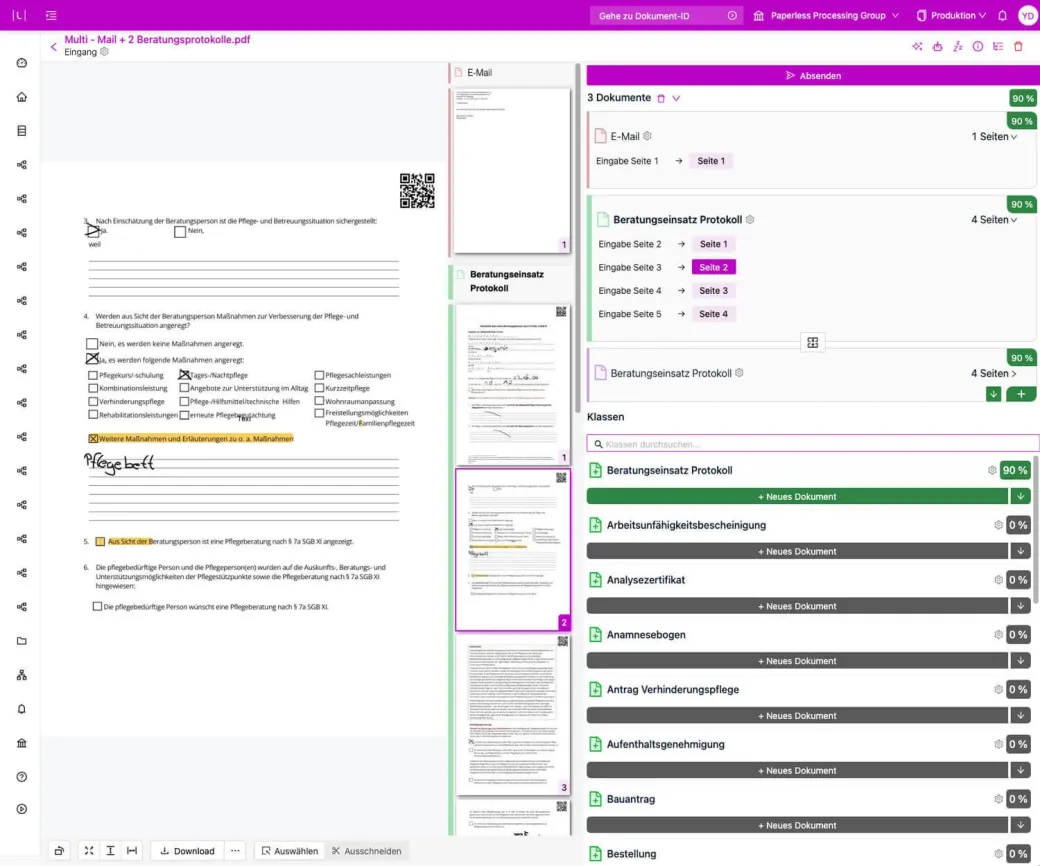
Classification & separation
Based on your own description of the document structure.

Powered by state-of-the-art generative AI models
No separator sheets or stamps required
Reliable recognition even for photos & handwriting
Inbox · 6 pages
3 documents detected
Invoice · 1 page
3 fields verified
Invoice Invoice no.RE-2026-0815 Date12.03.2026 IBAN DE00 0000 0000 0000 0000 00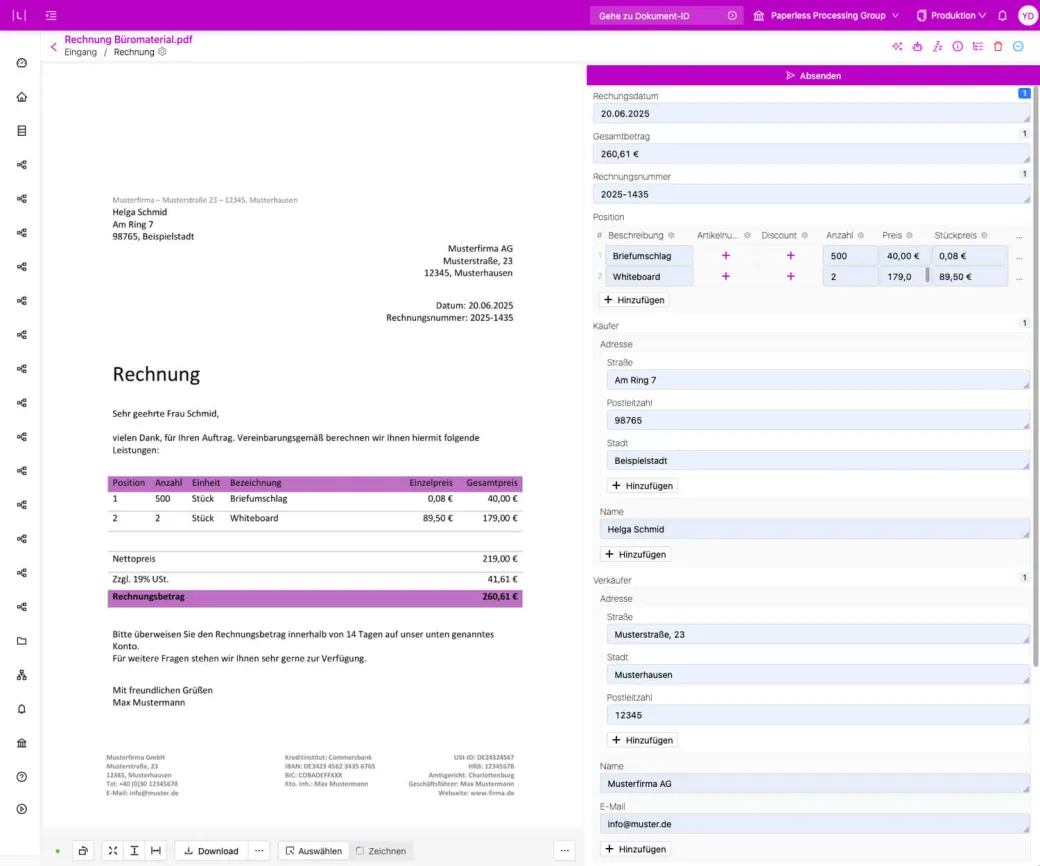
Deep extraction
Extraction of the relevant information based on your description
Precise processing of complex, unstructured documents
Recognition of handwritten content, too
Multimodal models that process both text and images
Simple. Scalable. Measurable.

How does lector work?
Automate the handling ofcases
Lector turns a full inbox into an automated workflow. Incoming mails and files are classified, split into individual documents and sorted by type; blank pages are removed and rotations corrected.
Lector extracts the relevant data from every document, including handwriting and markings. Incoming documents land exactly where they belong: in target systems such as CRM, line-of-business applications or DMS. You can review results, or have them processed fully automatically above a confidence threshold you choose yourself.
Manual sorting and forwarding disappear, and your inbox stays cleared day by day instead of piling up.
Lector checks incoming applications and forms for completeness and plausibility, regardless of layout or document type. Using your review criteria, Lector recognises filled and empty fields — including handwriting, ticked boxes and digital markings — reports what is missing, and checks whether the details are consistent, logical and up to date.
Required attachments are checked too, such as payslips, registration certificates or signed application forms. Missing or illegible documents stand out immediately, and a compact summary highlights inconsistencies between documents.
Your case handlers no longer have to work through every page only to discover at the end that something is missing. Lector does the groundwork so the application can be processed quickly. Manual review is supported so thoroughly that only minimal effort remains.
Lector reads structured, semi-structured and unstructured documents and extracts exactly the information you need — from names and dates of birth to invoice numbers, amounts and line items, right through to signatures and checkboxes. Handwriting, optical markings and multi-page documents are no problem either, entirely without OCR rules or templates.
With certain AI models you can see for every value how confident Lector is. Instead of typing data in by hand, only the actual case work remains — with high data quality and minimal rework.
Lector sorts and distributes incoming emails automatically, whether it's a job application, an invoice or a customer enquiry. Lector evaluates not just the message text but the attachments and their content, and forwards every mail to the right person, department or system.
You define the routing rules yourself — by sender, content, document type or extracted data. Every mail ends up where it belongs without manual distribution, and nothing is left sitting around.
Why Lector
Lector vs. chatbots
A chatbot answers questions about documents.
Lector processes documents autonomously.
| Capabilities | chatbots |  |
|---|---|---|
| Understands documents |  |
|
| Answers questions about documents | |
|
| Extracts relevant data |  |
|
| Classifies documents automatically |  |
|
| Validates content & rules | |
|
| Handles cases autonomously | |
|
| Hands results to line-of-business systems | |
|
| Processes thousands of documents per month | |
|
| Traceable & auditable | |
|
Build or buy
Lector vs. building it yourself
Azure Document Intelligence, AWS Textract & Co. are powerful tools – but tools. You get building blocks, not a finished house. Everything that turns building blocks into a document factory is already in Lector.
| Topic | Build it yourself with Azure, AWS & Co. | |
|---|---|---|
| Models & providers | Connect every provider separately; manage keys, rate limits, pricing and model changes yourself | Multi-model router: Gemini, GPT, Claude, Mistral, Qwen & Co. via Vertex AI, Azure, OVHcloud and Scaleway – selectable per step at a click, switching without rebuilding |
| Measuring quality | Set up test sets, metrics and comparisons by hand – or not at all | Evaluation Center: verified reference datasets, metrics per document class, confusion matrices, model and configuration comparison on real documents |
| Prompts & configuration | Prompt engineering by hand, iterating without tooling | Configuration assistant: an agent that creates document classes and fields from your description and improves prompts from your case handlers’ corrections |
| Scaling | Design and run your own architecture for queues, parallelism and autoscaling | Kafka-based processing: Kubernetes autoscaling, 10,000+ parallel sessions, millions of pages a month – without re-architecture |
| Integration into downstream systems | Program and maintain every export and connection yourself | Integration library: webhook and REST pull, email, DMS/ECM (e.g. d.velop, enaio), case-management systems via API, databases, RPA (UiPath, Power Automate) |
| Traceability | Build logging, history and UI yourself | Audit trail: every operation on every document – classification, correction, export – logged immutably, searchable and exportable |
| Document skills | Develop classification, separation, extraction and validation yourself | Built in: separating bundled PDFs, classification, extraction, master-data matching, completeness checks – from years of project experience |
| Governance & compliance | Assemble DPA, TOMs, no-training evidence and guardrails yourself | Out of the box: GDPR-compliant, EU hosting, no-training evidence per provider, document-specific guardrails, EU AI Act classification |
| Operations & updates | A team that keeps at it: model changes, refactoring, monitoring | We take care of it: continuous updates, monitoring of system and AI components, with an SLA if you want one |
“The market and infrastructure around LLMs are as dynamic as it gets. With Lector we outsource the ‘chasing the technology’.”
Head of IT at a Lector customer